title: “AI Tool Guide” description: “Technical guide and comparison.” date: 2026-06-02T00:00:00+08:00 lastmod: 2026-06-02T00:00:00+08:00 tech_stack: [] application_domain: Llm Frameworks source_version: ’' licensing_model: Open Source license_type: MIT file_size: ’' file_md5: ’' download_url: ’' backup_url: ’' last_maintained: “2026-06-02” draft: false categories: [“llm-frameworks”] tags: ["] aliases:
- /posts/promptfoo-llm-frameworks-2026/
faqs: - q: ‘How do I install and run promptfoo locally?’
a: ‘The quickest path needs no install:
bash npx promptfoo@latest init --example getting-startedTo install globally", “usenpm install -g promptfoo(orbrew install promptfoo”, “orpip install promptfoo). Then runpromptfoo evalto evaluate andpromptfoo viewto open the local viewer.’ - q: ‘Can I use promptfoo with my own AI models?’
a: ‘Yes. Promptfoo supports many providers — OpenAI”, “Anthropic”, “Google”, “DeepSeek”, “local models”, “and more. You declare each one in the
providerslist of yourpromptfooconfig.yamland supply the matching API key via environment variables.’ - q: ‘How does promptfoo compare performance across different models?’
a: ‘You list several entries under
providers”, “and promptfoo runs every prompt and test case against each one.promptfoo viewthen shows the outputs side by side with pass/fail per assertion”, “so you can compare quality directly on your own inputs.’ - q: ‘Is there a way to integrate promptfoo with CI/CD pipelines?’
a: ‘Yes. Because promptfoo is a CLI”, “you can run
npx promptfoo@latest evalin any pipeline. It’’s commonly wired into GitHub Actions so every push or pull request runs your evaluation suite.’ - q: ‘How do I contribute to the promptfoo project?’ a: ‘Contributions are welcome. Open an issue or submit a pull request on GitHub. See the contributing guidelines” for details.’—
Introduction
If you build with models like GPT, Claude, Gemini, or DeepSeek, you know that “looks good in the playground” is not the same as “works reliably in production.” Promptfoo is an open-source CLI and library for evaluating and red-teaming LLM applications. It replaces the trial-and-error approach with declarative test configs you can run locally and wire into CI/CD. In this guide we’ll install it, write a promptfooconfig.yaml, run an evaluation, compare models, and kick off a red-team scan.
What Is Promptfoo?
Promptfoo is a CLI and library for evaluating and red-teaming LLM apps. You describe your prompts, the providers (models) you want to run them against, and a set of test cases with assertions. Promptfoo runs every prompt through every test case, checks the assertions, and gives you a side-by-side view of how each model performed.
Its core capabilities are: - Evaluation — run prompts across multiple providers and grade outputs with assertions (exact match, contains, semantic similarity, LLM-graded rubrics, and more).
- Model comparison — compare GPT, Claude, Gemini, DeepSeek, and others on the same inputs.
- Red teaming — generate adversarial test cases to probe your app for vulnerabilities before shipping.
- CI/CD integration — declarative configs run anywhere your terminal does, including GitHub Actions.
The project is written in TypeScript, distributed under the MIT license, and maintained by the promptfoo team.
How Promptfoo Works
The workflow is config-first: 1. Declarative configuration — a single promptfooconfig.yaml defines your prompts, providers, and tests. No glue code required for the common cases.
Command line interface (CLI) —
promptfoo evalruns the evaluation. It prints a results table to your terminal and stores results locally.Local web viewer —
promptfoo viewopens a local web UI that visualizes the eval results so you can compare outputs cell by cell.
Here’s a minimal promptfooconfig.yaml: ````yaml
promptfooconfig.yaml
description: “Technical guide and comparison.” prompts: - “What is the capital of ?”
- “Explain quantum mechanics in one sentence.”
providers: - openai:gpt-4o-mini
- anthropic:messages:claude-3-5-sonnet-20241022
tests: - vars: country: France assert: - type: contains value: Paris
This config runs both prompts against both providers. For the first prompt it substitutes ```` and asserts that the output contains "Paris." API keys are read from environment variables (for example ``OPENAI_API_KEY`` and ``ANTHROPIC_API_KEY``), not stored in the config.

- Source Code: [promptfoo GitHub](https://github.com/promptfoo/promptfoo)
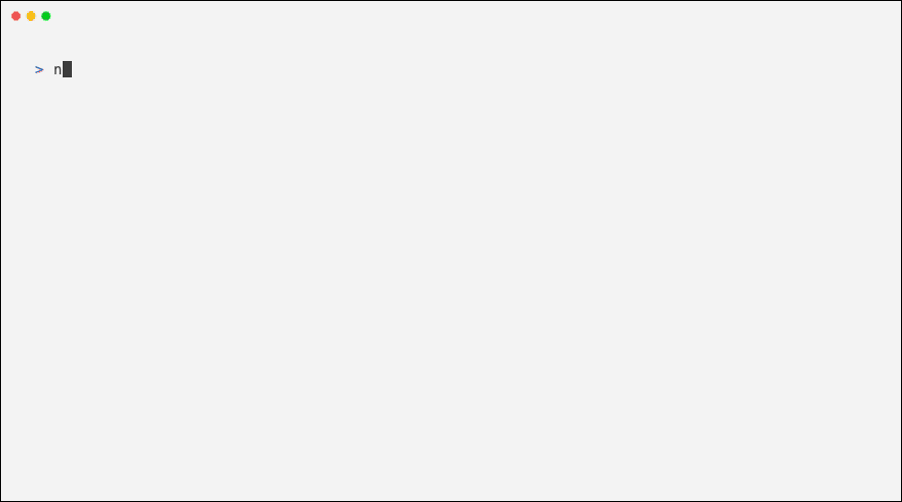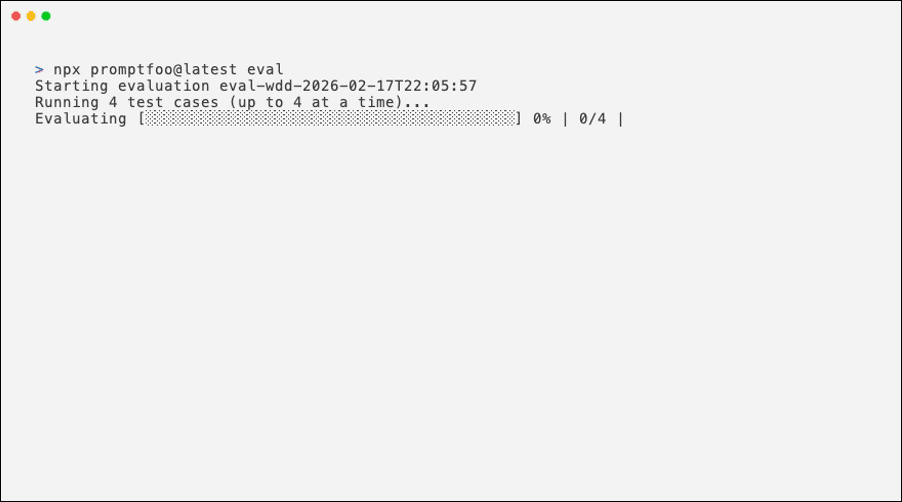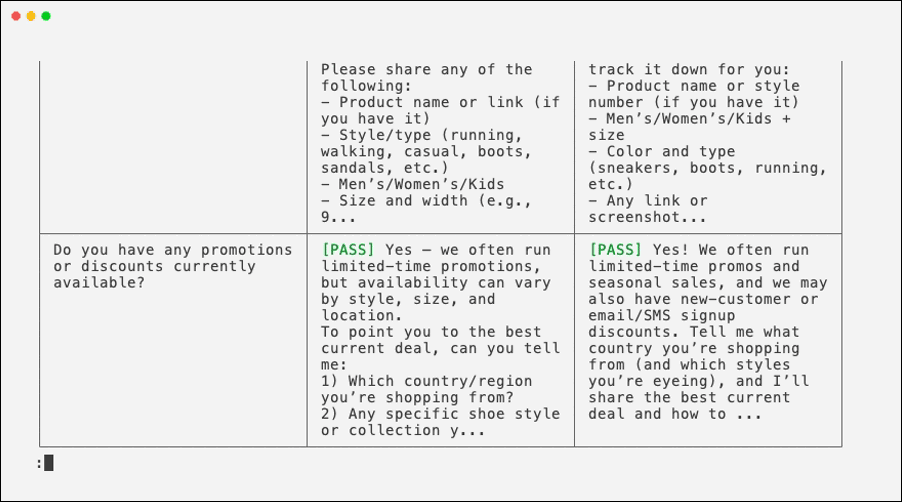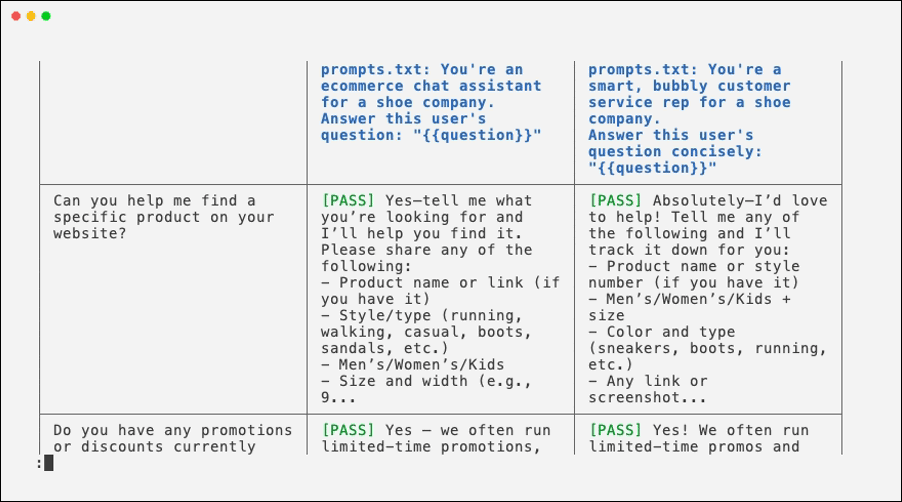
*promptfoo self-grading view (source: promptfoo/promptfoo repo, via dibi8 analysis)*
## Installation & Setup
If you want to run promptfoo as a scheduled production job, you'll want an always-on box — spin one up on [DigitalOcean](https://m.do.co/c/eca87ac14ee0) (free trial credit for new accounts), or [HTStack](https://my.htstack.com/aff.php?aff=27187) for a low-latency Hong Kong VPS (the same IDC that hosts dibi8.com).
Promptfoo needs Node.js ``^20.20.0`` or ``>=22.22.0``. Check your version: `````bash
node -v
If you need Node.js, grab it from the official website.
Install
The fastest way to try promptfoo is with no install at all: `````bash npx promptfoo@latest init –example getting-started
To install it globally instead, pick whichever fits your environment: `````bash
# npm
npm install -g promptfoo

# Homebrew
brew install promptfoo

# pip
pip install promptfoo
Set your API key
Promptfoo reads provider credentials from environment variables. For OpenAI: `````bash export OPENAI_API_KEY=sk-abc123
Use the matching variable for whichever provider you're testing (for example ``ANTHROPIC_API_KEY`` for Claude). If you forget to set the key, you'll see an authentication error from the provider when you run an eval — set the variable and re-run.

### Running your first evaluation

After ``init``, you'll have a ``promptfooconfig.yaml`` in your directory. Run the eval and open the viewer: `````bash
promptfoo eval
promptfoo view
promptfoo eval prints the results to your terminal; promptfoo view opens a local web UI for a richer side-by-side comparison. If you get stuck, check the documentation or open an issue on GitHub.
Core Usage
Example 1: A simple assertion
Create a config that checks an expected substring: `````yaml
promptfooconfig.yaml
description: “Technical guide and comparison.” prompts: - “What is the capital of ?”
providers: - openai:gpt-4o-mini
tests: - vars: country: France assert: - type: contains value: Paris
Run it: `````bash
promptfoo eval
Promptfoo executes the test case and reports whether the assertion passed.
Example 2: Comparing models with multiple assertion types
You can list several providers and mix assertion types — exact, semantic, and LLM-graded: `````yaml
promptfooconfig.yaml
description: “Technical guide and comparison.” prompts: - “Answer concisely: "
providers: - openai:gpt-4o
- anthropic:messages:claude-3-5-sonnet-20241022
defaultTest: assert: - type: llm-rubric value: does not describe itself as an AI, model, or chatbot
tests: - vars: question: “What is the meaning of life?” assert: - type: similar value: “It depends on the person” threshold: 0.6
Run the same command and ``promptfoo view`` to compare both models cell by cell: `````bash
promptfoo eval
Example 3: Running in a CI/CD pipeline
Promptfoo runs anywhere your terminal does. Here’s a GitHub Actions workflow that fails the build if assertions fail: `````yaml
.github/workflows/eval.yml
name: Promptfoo Eval
on: push: branches: [ main ] pull_request: branches: [ main ]
jobs: eval: runs-on: ubuntu-latest steps: - name: Checkout repository uses: actions/checkout@v4
  - name: Set up Node.js
    uses: actions/setup-node@v4
    with: node-version: 22

  - name: Run promptfoo eval
    env: OPENAI_API_KEY: $
    run: npx promptfoo@latest eval
This runs your evaluation on every push and pull request, catching regressions before they merge.

## Red Teaming

Beyond plain evaluation, promptfoo can generate adversarial test cases to probe your app for vulnerabilities such as prompt injection, jailbreaks, and unsafe outputs. The red-team workflow has its own subcommands: `````bash
# Launch the setup UI to configure your target and attack types
npx promptfoo@latest redteam setup

# Or configure without the GUI
promptfoo redteam init --no-gui

# Generate adversarial cases and run them against your target
promptfoo redteam run

# View the findings report
promptfoo redteam report
The report groups findings by vulnerability category and severity, with suggested mitigations.
Benchmarks & Real-World Use
Promptfoo is widely used for prompt and model evaluation. Rather than relying on a single leaderboard, the point of the tool is that you benchmark on your own prompts and test cases — the numbers that matter are the ones from your application, not a generic suite.
A typical workflow looks like this: `````bash npx promptfoo@latest eval && npx promptfoo@latest view
Run your full test set across the candidate models, then open the viewer to see exactly which prompts and which cases each model passed or failed. Because the config is declarative, the same suite runs locally during development and in CI on every commit.

*promptfoo red team dashboard (source: promptfoo/promptfoo repo, via dibi8 analysis)*
## Comparison with Alternatives
See also our [related open-source tools](dibi8-internal-link) coverage.
When you're choosing an LLM evaluation and red-teaming tool, promptfoo's combination of a declarative config, local-first workflow, and built-in red teaming is its main draw.
| Feature | promptfoo |
|
---
|
* * *
|
| **Stars** | 21,825 |
| **License** | MIT |
| **Maintainer** | promptfoo |
| **Language** | TypeScript |
| **Default branch** | main |
| **Config style** | Declarative ````promptfooconfig.yaml```` (prompts / providers / tests / assert) |
| **Interfaces** | CLI (````promptfoo eval```` / ````view````) plus library use |
| **Model coverage** | GPT, Claude, Gemini, DeepSeek, and many more providers |
| **Red teaming** | Built in (````promptfoo redteam```` subcommands) |
| **CI/CD** | Runs in any terminal; first-class GitHub Actions usage |
### Detailed breakdown
- **Stars** — promptfoo has roughly 21,825 stars on GitHub, a strong signal of adoption among LLM developers.
- **Declarative configs** — defining tests in ````promptfooconfig.yaml```` keeps your evaluation suite versioned alongside your code, so the same checks run locally and in CI.
## Limitations & Honest Assessment
Promptfoo is a capable tool, but it's worth knowing the tradeoffs: 1. **Config grows with complexity** — the declarative format is great for the common case, but large suites with many providers, dynamic vars, and custom assertions get verbose. You"ll often factor prompts and test cases into separate files.
2. **You bring your own model access** — promptfoo orchestrates evals but relies on your provider API keys and quotas. Costs and rate limits are on you.
3. **Eval runs cost tokens and time** — a broad suite across several providers makes a lot of API calls. On large test sets that adds up in both latency and spend.
4. **Assertion design takes thought** — LLM-graded rubrics (````llm-rubric````) and semantic checks are powerful but non-deterministic; getting reliable, meaningful assertions takes iteration.
5. **Actively evolving** — promptfoo ships frequently. That means fast improvements, but also occasional breaking changes; pin a version in CI for stability.
These are the kinds of considerations to weigh before standardizing on it.
## Conclusion
Promptfoo turns prompt and model testing from guesswork into a repeatable, version-controlled process. With a single ````promptfooconfig.yaml````, you can evaluate prompts, compare GPT, Claude, Gemini, and DeepSeek on your own data, and red-team your app for vulnerabilities — all from the CLI and inside CI/CD. The best next step is to run ````npx promptfoo@latest init --example getting-started```, point it at your prompts, and open the viewer to see how your models actually perform.
Large-scale scraping needs rotating proxies — [WebShare](https://www.webshare.io/?referral_code=oa14d5f0wx4f) is the standard choice.
- Join the [dibi8 English Telegram group](https://t.me/DIBI8_Group/2) for open-source AI tool drops.
- Read next: [related guides on dibi8](dibi8-internal-link).
* * *
**Sources & Further Reading**: - GitHub repository: https://github.com/promptfoo/promptfoo
- Official docs / README: https://github.com/promptfoo/promptfoo#readme
*Some links above are affiliate links. dibi8.com may earn a commission if you sign up, at no extra cost to you. Helps keep the site running and the content free.*
related open-source tools -> ai-tools-directory
related guides on dibi8 -> ai-coding-agent-landscape-2026-skills-mcp-opensource
{
"@context": "https://schema.org",
"@type": "Article",
"headline": "Promptfoo: Test, Evaluate & Red-Team Your LLM Prompts — Practical 2026 Guide",
"datePublished": "2026-06-02",
"dateModified": "2026-06-02",
"author": {
"@type": "Organization",
"name": "Dibi8"
},
"publisher": {
"@type": "Organization",
"name": "Dibi8",
"logo": {
"@type": "ImageObject",
"url": "https://dibi8.com/logo.png"
}
},
"mainEntityOfPage": {
"@type": "WebPage",
"@id": "https://dibi8.com/resources/promptfoo-llm-frameworks-2026"
}
}
</script>
## Frequently Asked Questions (FAQ)
**问:LangChain和LlamaIndex哪个更好?**
LangChain适合复杂工作流和Agent构建,LlamaIndex专注于RAG和数据检索优化。
**问:如何评估LLM框架的性能?**
基准测试包括:推理速度、准确率、资源消耗、可扩展性。
**问:开源LLM框架的商业使用限制?**
大多数采用MIT/Apache许可,可商业使用,但需保留版权信息。
**问:是否需要GPU才能运行LLM框架?**
推理需要GPU以获得最佳性能,但部分框架支持CPU模式(较慢)。
**问:企业级部署的最佳实践?**
使用Kubernetes容器化、API网关、监控告警、自动伸缩、以及灰度发布。
* * *